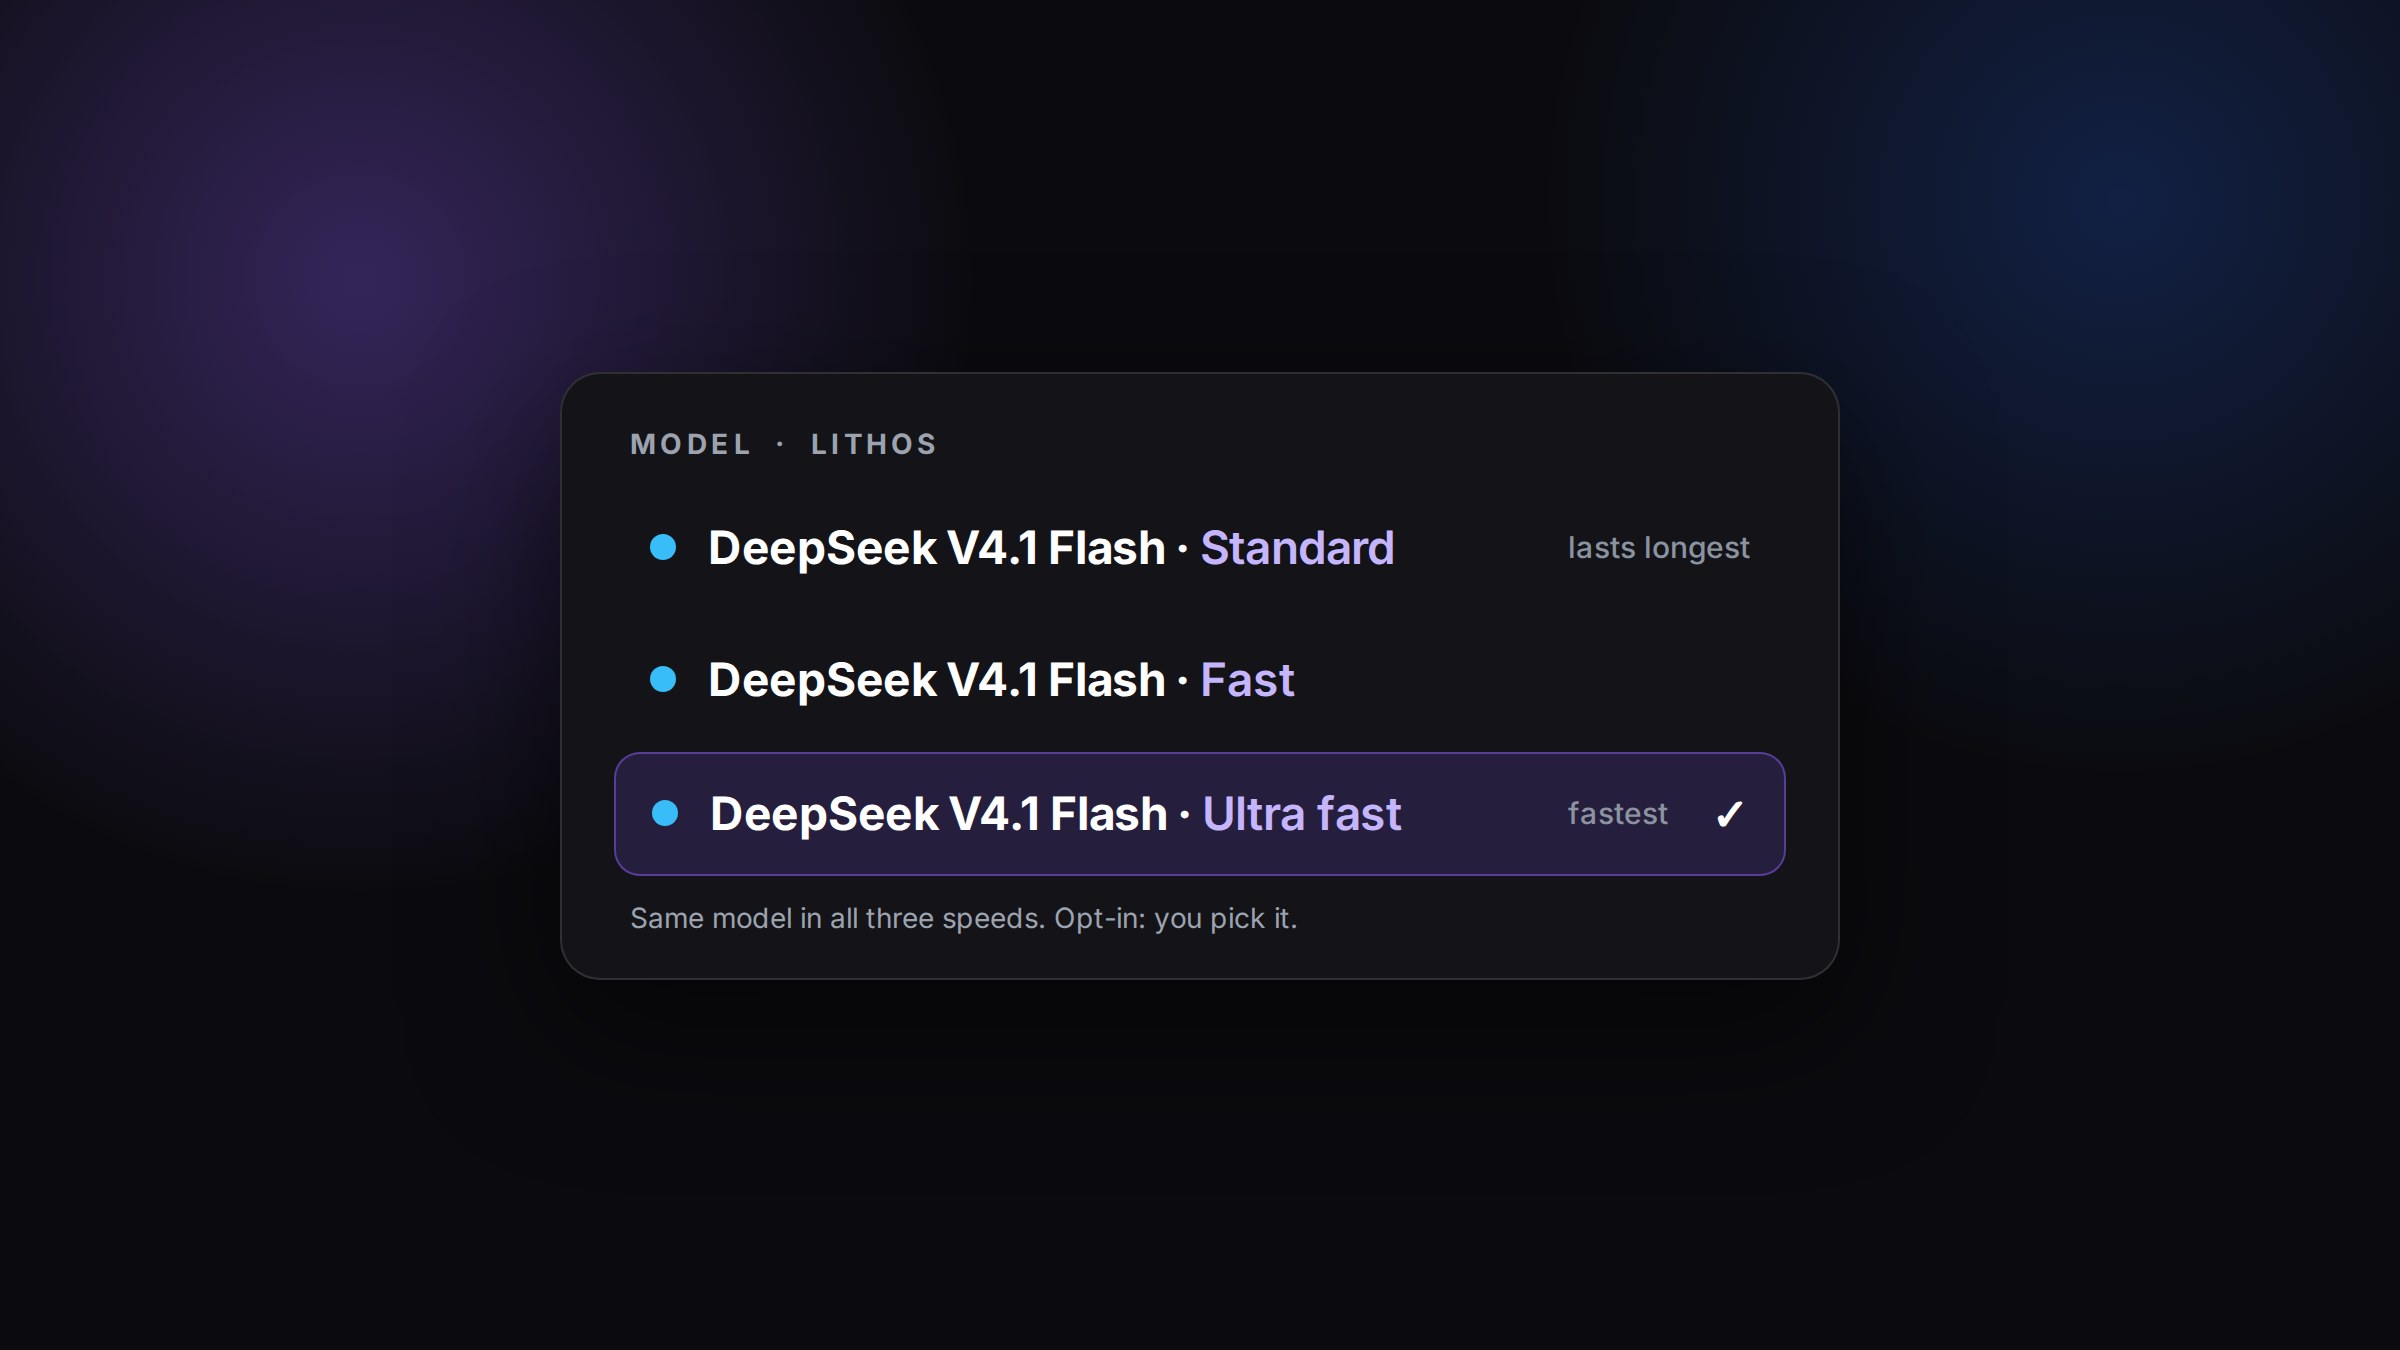
Every CRHQ server can now use DeepSeek V4.1 Flash. It is a model made by DeepSeek and run for us by Lithos, an inference provider built for fast answers. In the model picker you will find it as DeepSeek V4.1 Flash, with Lithos shown as the provider.
We are running this as a trial, and we would like your opinion.
What you get
- The model. DeepSeek V4.1 Flash is DeepSeek's model, served by Lithos. CRHQ did not build or train it; we make it available on your server.
- Your choice of speed. Pick one of three speeds in the model picker: DeepSeek V4.1 Flash · Standard, · Fast or · Ultra fast. It is the same model at full quality in all three; only the speed changes (Lithos gives about 250, 350 and 450+ tokens per second). A faster speed uses the monthly allowance faster: Standard lasts about 2.3 times as long as Ultra fast.
- Opt-in. Nothing switches to it by itself, and it never becomes a server's or an agent's default. Your agents and sessions keep their current model until you pick DeepSeek V4.1 Flash in the model picker, or an admin picks it for an agent.
- Covered by CRHQ, for now. While the trial lasts, each server gets a monthly allowance for this model, and CRHQ pays for it. Your other models and your own plans are unaffected.
How to try it
- Start a new session, or open an agent's settings.
- In the model picker, choose DeepSeek V4.1 Flash (provider: Lithos) and pick a speed.
- Use it as you would any other model, and compare it with the one you use today.
Where your prompts go
Requests to DeepSeek V4.1 Flash pass through CRHQ's servers and are processed by Lithos AI, a third-party provider. Lithos has not yet given us written terms on how it handles prompts (whether it stores them, for how long, or uses them for training), so we cannot promise how your data is treated there. Do not use it for confidential, personal or client data. If your work involves data you cannot share with an outside provider, keep using your current model for that work.
Tell us what you think
This is a trial, and your answers decide what happens next. Would you like fast-inference models like this one, and DeepSeek V4.1 in particular, to become a permanent part of CRHQ? Reply to the announcement email or tell us in the CRHQ community.
Good to know
- It is a trial. It runs for a limited time, and the allowance may change while it runs.
- Your monthly use. Settings > AI Models > Lithos shows how much of this month's allowance your server has used.
- When the allowance is used up. You see a message saying your server has used this month's allowance for DeepSeek V4.1 Flash. It renews on the 1st of next month. Until then, choose another model, or connect your own AI provider under Settings > AI Models.
- If the trial's monthly budget runs out. DeepSeek V4.1 Flash pauses for everyone until the 1st of next month, with a message saying so. Your other models keep working.
| Fact | Value |
|---|---|
| Availability | Every CRHQ server |
| Model | DeepSeek V4.1 Flash, made by DeepSeek |
| Provider | Lithos (third party) |
| Cost to you | None while the trial lasts, up to a monthly allowance per server |
| Client action required | None. It is opt-in: pick it in the model picker to try it |