GPT-6.1 Sol is now selectable on your CRHQ server. It is OpenAI's upgrade to GPT-6 Sol, and it brings near-Astra results on coding, computer use and professional work to Sol's everyday price.
Near-Astra results at a fifth of the price
OpenAI published each result as a score and a cost per task at five reasoning settings, from low to max. The chart shows each model's best score across those settings, together with what that run cost.
| Benchmark | GPT-6.1 Sol | GPT-6 Astra | GPT-6 Sol |
|---|---|---|---|
| DeepSWE v1.1 | 75.2% ($0.65 per task) | 74.1% ($4.43 per task) | 68.8% ($2.74 per task) |
| OSWorld 2.0 (offline set) | 71.4% ($1.27 per task) | 73.5% ($9.44 per task) | 64.4% ($3.37 per task) |
| GDP.pdf | 32.0% ($0.35 per task) | 32.2% ($1.91 per task) | 28.0% ($0.35 per task) |
| AutomationBench | 36.1% ($0.30 per task) | 41.4% ($1.73 per task) | 33.2% ($0.27 per task) |
| Terminal-Bench Science 0.1 | 57.0% ($5.47 per task) | 68.1% ($23.80 per task) | 27.6% ($12.18 per task) |
The standout is DeepSWE, which tests long software engineering tasks in real codebases: GPT-6.1 Sol scores 75.2%, just ahead of GPT-6 Astra, at about a fifth of the cost per task. On computer use it lands within about two points of Astra, and on scientific workflows it more than doubles GPT-6 Sol.
OpenAI is also clear about where Astra still wins: GPT-6 Astra has the highest score on Terminal-Bench Science, and OpenAI recommends it for the most difficult scientific research. Our suggestion is to use GPT-6.1 Sol as your everyday GPT model and keep Astra for the hardest problems.
GPT-6.1 Sol also makes fewer factual mistakes. On a deliberately difficult set of prompts, its share of answers with a factual error drops from 11.4% to 7.7% at low reasoning effort, compared with GPT-6 Sol.
Pricing
| Per 1M tokens | GPT-6.1 Sol | GPT-6 Astra | GPT-6 Sol |
|---|---|---|---|
| Input | $2.00 | $10.00 | $2.00 |
| Cached input | $0.10 | $1.00 | $0.20 |
| Output | $10.00 | $50.00 | $10.00 |
GPT-6.1 Sol has a context window of about 1 million tokens, can write up to 128,000 tokens in one reply, and has a knowledge cutoff of April 2026. These are equivalent token values based on OpenAI's published rates. Actual billing runs through your own OpenAI or Codex plan.
How to use it
- Start a new session, or edit an agent's default model.
- Choose provider Codex.
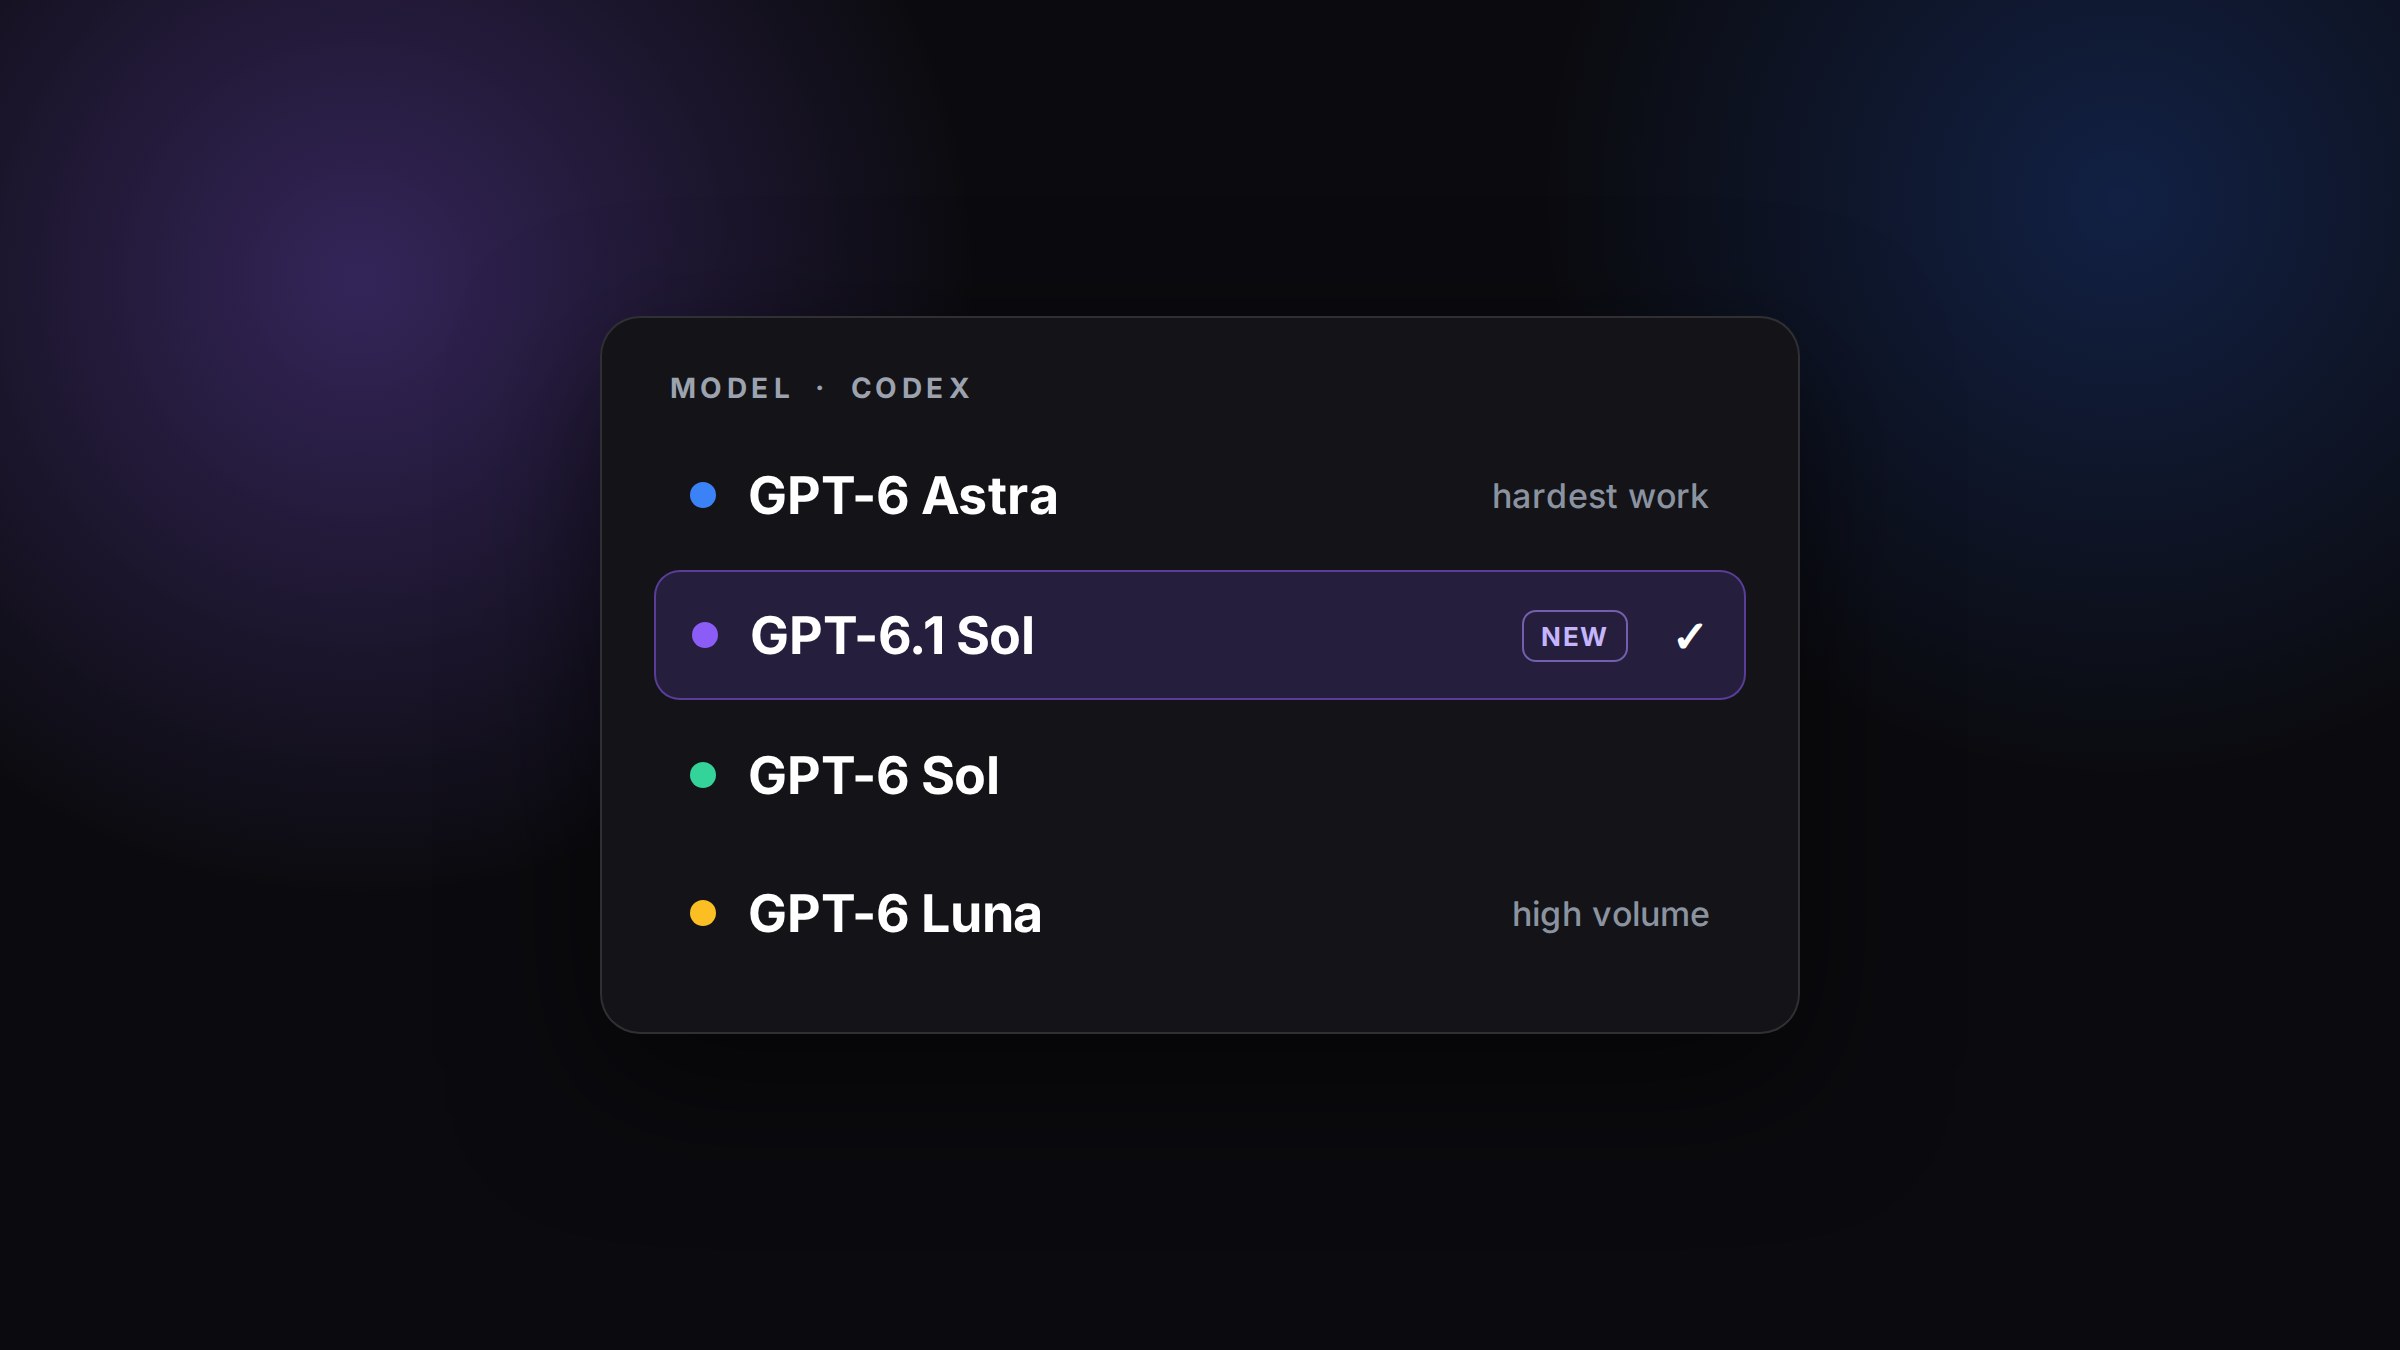
- Pick GPT-6.1 Sol from the dropdown. You will find it right after GPT-6 Astra.
- Send your message as normal. Artifacts, skills and tools all work the same way.
In CRHQ, GPT-6.1 Sol starts at extra-high reasoning effort, our default for Sol models. Per-turn cost appears in each session's Costs tab.
GPT-6.1 Sol needs Codex connected to an OpenAI Plus, Pro, Business, Enterprise or Edu plan. On Enterprise and Edu, an admin has to switch it on in OpenAI first.
Availability
| Fact | Value |
|---|---|
| Availability | Every CRHQ server with Codex connected to an eligible OpenAI plan |
| Live since | 2026-09-30 |
| Provider | Codex (OpenAI) |
| Pricing | $2 in / $10 out per 1M tokens; cached input $0.10 |
| Client action required | None on Plus, Pro and Business; Enterprise and Edu admins switch it on in OpenAI first |